
Semantic document search finds passages of text by their meaning rather than by the character strings used. To do this, documents are split into passages, and these passages are converted into vectors, known as embeddings, which represent closeness in content as distance. The search query is converted into the same space, and the search looks for the nearest passages. This allows the method to find passages that use different wording from the question. It is usually combined with exact full-text search.
Where the term comes from and where it is standardised
The wish to search by meaning rather than word form is as old as information retrieval itself. It became practical when trained models could convert text passages into vectors that represent similarity in content as geometric proximity. A widely cited reference paper on this is Dense Passage Retrieval by Karpukhin and others from 2020. It explicitly compares the method with a full-text search based on BM25, the ranking method that has shaped lexical search since the 1990s.
In German usage, semantic search, vector search and dense retrieval are largely used interchangeably. The term semantic document search emphasises the use case: what is searched is a document collection, not a database with fields.
Putting the term in context
There is no standard and no binding definition for semantic document search. The linked papers document the methods, not the term. Nor is there a fixed threshold for the share of semantic methods at which a system may call itself that.
How the method works
Chunking
A whole document is too coarse as a search unit. A forty-page framework agreement deals with many things, and its overall meaning is blurred. That is why the text is first split into passages. How this splitting turns out helps determine the quality of all later results: passages that are too small lose their context, and passages that are too large dilute the meaning. Common methods cut along headings and paragraphs and let the passages overlap slightly so that a sentence at the cut edge is not lost.
Embeddings and distance
Each passage is converted by a model into a vector, a sequence of numbers of fixed length. These representations are called embeddings. They are trained so that texts with similar content lie close to each other. The search query passes through the same model and ends up in the same space. The search then looks for similar passages, for example using cosine similarity. This corresponds to the cosine of the angle between two vectors.
With a few thousand passages, every distance could be calculated individually. With millions, that is too slow, so approximation methods are used that only examine part of the space. They do not guarantee the best results, but very probably very good ones. This imprecision is a deliberate design decision, not a flaw.
Combination with full-text search
In practice, search is rarely purely semantic. Lexical search is hard to beat for case reference numbers, document numbers, product codes and proper names, because there the character string itself carries the meaning. It is therefore common practice to generate both lists of results and merge them. The term hybrid retrieval has become established for this. Often a second step follows in which an additional model re-sorts the shortlist.
What components and providers exist
A semantic search pipeline consists of three interchangeable parts. They can come from different providers and run in different locations.
- The embedding model: operated either as a service via an interface or locally on your own hardware. This decision determines whether document content leaves your own data centre.
- The vector store: as an extension of an existing database, such as pgvector for PostgreSQL, as a library like FAISS, or as a standalone service. The choice affects operation and scaling, rarely the quality of results.
- The lexical index for the hybrid part: as a rule, a system from the Lucene family, i.e. Elasticsearch, OpenSearch or Apache Solr.
If a language model then processes the results into a written answer, a fourth component is added. This architecture is called RAG, and it is described in a primary source of its own.
How Nexoria implements this
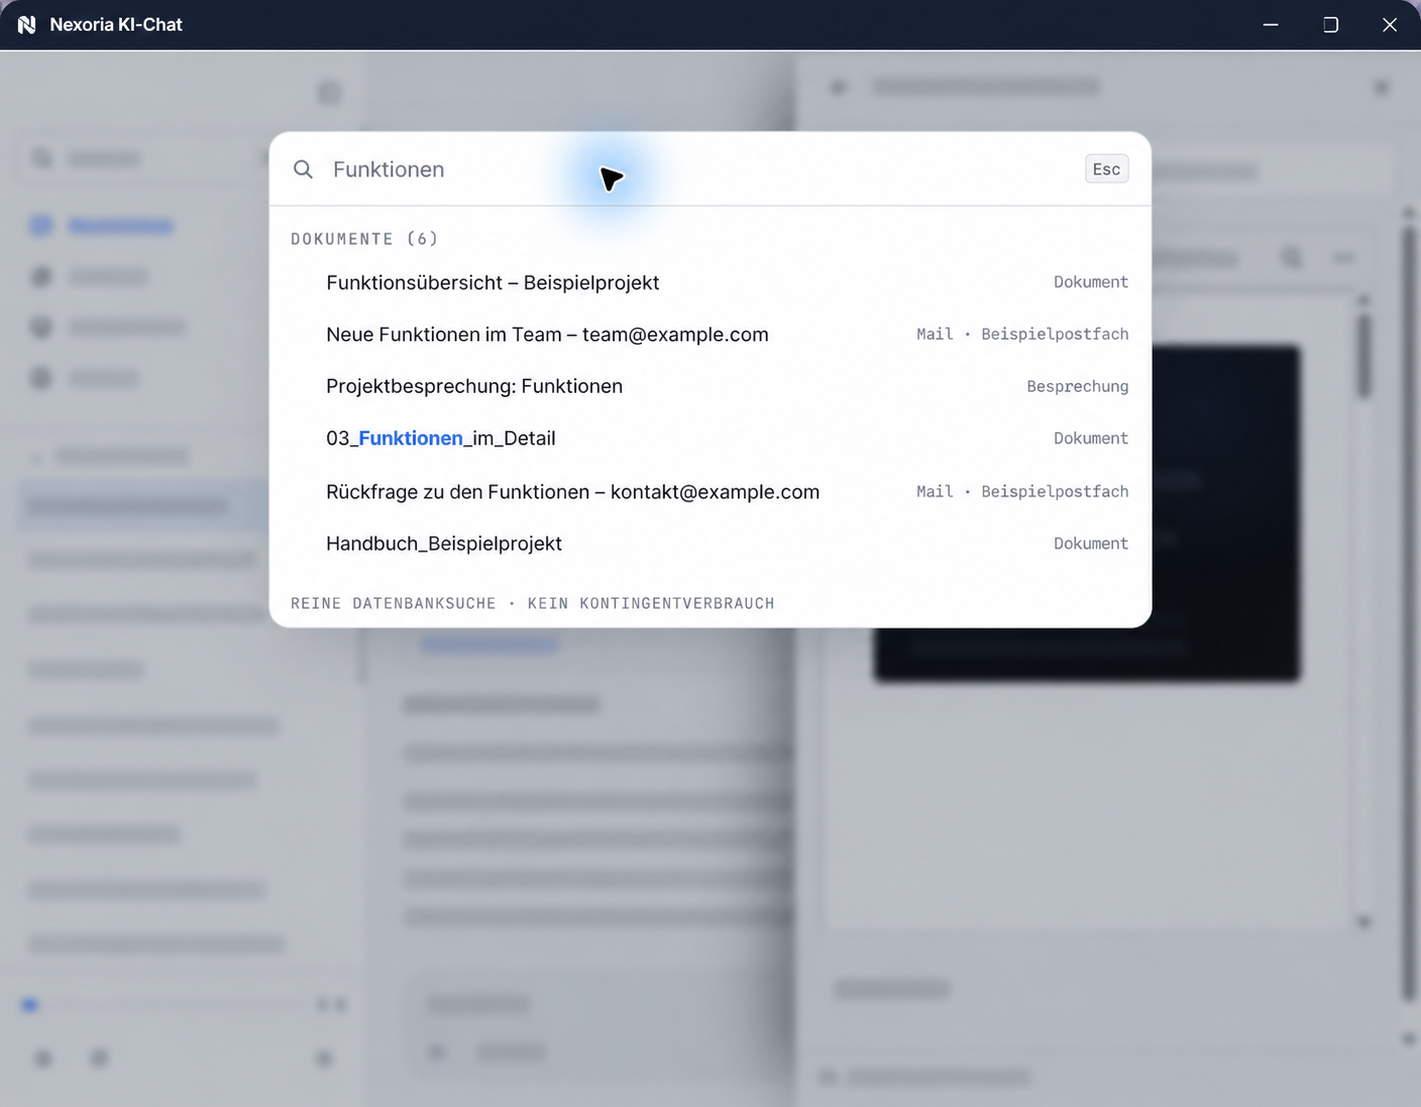
In the platform, the method bears the product name Document search. It works on the index that is created when files are stored in Nexoria Drive , and is available both in the assistant Nex and in a dedicated search window. Nexoria uses semantic search across the content of the workspace as well as RAG with hybrid retrieval, that is, the combination of lexical and semantic search.
Document search searches the contents of a workspace semantically and cites the source for every result.
As for where the embeddings are computed: Document embeddings and semantic search run on servers in Germany, using models that Nexoria operates there itself. Answer generation is separate from this and does not take place in the same location, see Data residency.
What matters in practice
- Similarity is not a measure of truth. A passage can be very close in content to the question and still contain the wrong information, for instance because it comes from a superseded version of a contract.
- For exact identifiers, semantic search is inferior to exact word search. Hence the combination of both methods, not the replacement of one by the other.
- The ranking can no longer be explained by individual words. It results from a distance value, which makes troubleshooting harder.
- Scans without a text layer and audio recordings are first converted into text for the search, at Nexoria via speech and text recognition.
Sources
As of
- Karpukhin et al., Dense Passage Retrieval for Open-Domain Question Answering. Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), preprint on arXiv, 2020. https://arxiv.org/abs/2004.04906 Retrieved on .Describes search using learned vector representations of text passages, the method behind semantic search. The paper explicitly compares it with BM25 full-text search.
- Robertson and Zaragoza, The Probabilistic Relevance Framework: BM25 and Beyond. Foundations and Trends in Information Retrieval, now publishers, 2009. https://www.nowpublishers.com/article/Details/INR-019 Retrieved on .Summary of the BM25 ranking method by its creators. Source for how lexical full-text search works, as described in the text.
- Lewis et al., Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. Advances in Neural Information Processing Systems 33 (NeurIPS 2020), preprint on arXiv, 2020. https://arxiv.org/abs/2005.11401 Retrieved on .The first description of the RAG method. It introduces the name and describes the combination of a retrieval step with a generative model.
As of